This is part 4 of a 4-part series on restructuring engineering documentation with an AI teammate.
- The messy truth about restructuring engineering docs with an AI teammate – link
- Stitching five documentation frameworks into one coherent engineering wiki – link
- Your Confluence should be a derived read model over your repo –
link - Codifying your reorg: playbooks as the shared interface for humans and AI teammates – you're here
Playbook as an interface
A playbook is one document. A human on their first day can read it and do the work. An AI agent, given the same document, can do the same work. Both benefit from the same clarity: the phases named, the prerequisites listed, the gotchas surfaced, the verification steps spelled out. That is the whole idea.
It sounds obvious. It is not what most teams do. Most teams keep runbooks for humans (assumed context, "you know what to do") and prompts for agents (imperative, one-shot, tightly scoped). Two sets of docs, both stale, neither testable by the other audience.
The closest published prior work we know of is Zack Proser's Claude Skills as Self-Documenting Runbooks. Proser makes the same core observation, that a well-written skill is an internal training runbook, and applies it to onboarding and internal-training use cases. What we add here: the docs-migration application (six weeks at scale, not a training scenario), the sandbox surprises we ran into dispatching agents across a multi-repo group, and the fork-versus-fresh distinction that mattered more than we expected. If you have read Proser's piece, skip to the multi-agent section. That is where this post earns its length.
How our playbooks were actually born
We did not sit down and design a playbook library. We did the work: restructure a section, publish a batch of pages, wire up a diagram pipeline. Then, when the same shape came around for the third time, we wrote it down.
The rule of three is worth stating plainly.
- First time: figure it out. Keep notes but nothing formal.
- Second time: notice the shape is repeating. Resist the urge to codify. One repetition might be coincidence.
- Third time: write the playbook.
Codifying after the fact is a feature, not a bug. A playbook written before the first run is a specification of what you think the work looks like. A playbook written after the third run is a specification of what the work actually is. The pre-run version misses the gotchas the actual work uncovered. The post-run version misses nothing important because the important things all bit us on runs one, two, or three.
Multi-agent orchestration lessons
Three lessons from six weeks of orchestrating agents at reorg scale. This section carries the most novelty relative to Proser's piece and the generic multi-agent literature.
Fan-out at scale. The 17-repo README rollout from Post 1 is the canonical example. One prompt describing the target docs/README.md shape, one dispatch, 17 fresh subagents in parallel, one afternoon. This works when the task is embarrassingly parallel: every repo's work is independent, no agent needs anything another agent produced. The trap is trying to fan out work that has hidden dependencies (shared inventory, cross-repo naming conventions being settled mid-flight). The rule we settled on: if you cannot describe the target shape without referring to another agent's output, do not fan out yet.
Fork versus fresh. Two dispatch modes, two use cases, easy to confuse.
- Fork the parent. The fork inherits the parent session's context: the framework choices from Post 2, the sync-map shape from Post 3, the vocabulary we have been building all afternoon. Use forks when the follow-up task depends on session history. A concrete example: "which pages in Architecture still reference the pre-2022 auth flow?" A forked agent already knows what the Architecture section is, what the auth flow was, and what the reorg is trying to achieve. It comes back with a punch list in minutes.
- Fresh subagent. Starts empty. No session context. Use fresh when the task is scoped, mechanical, and you want the agent uncontaminated by your own bias. A concrete example: the 17-repo README fan-out. Each agent reads only its repo and the prompt. It does not know what the other 16 are doing. That independence is the point. You get 17 independent grounded reads, not one repeated house style. If we had forked instead, all 17 outputs would have sounded suspiciously like the parent session's voice.
The failure mode is picking the wrong one. Fresh where you needed fork wastes an hour re-establishing context. Fork where you needed fresh gives you 17 landing pages that read like the same person wrote them, which defeats the point.
Sandbox surprises. Bash inside a dispatched subagent, on our setup, was restricted to the agent's current working directory by default. Fine for single-repo work; broken for cross-repo work. When we asked an agent to render diagrams from beacon-labs/catalog-service and drop the PNGs into a shared cache directory a level up, the copy calls were denied. The agent had no visible way to reach outside its assigned current working directory.
MCP tool calls were the workaround. MCP tools mostly do not need filesystem access: a Confluence upload happens over HTTP, a Jira issue read happens over HTTP, a Slack post happens over HTTP. Cross-repo work routed through MCP kept working. Cross-repo work routed through Bash did not.
The pattern we settled on: dispatch fewer, broader agents (one per repo group, not one per file); or make the current working directory the shared parent and pass repo paths as arguments; or use MCP-only agents for work that crosses filesystem boundaries. This would have saved a day if we had known it on the first dispatch.
Skills sit below playbooks
A playbook orchestrates. A skill is one thing.
Skills sit below playbooks in the codification stack. A playbook has phases, branching, and verification. It is a multi-step recipe. A skill is one atomic operation, invocable by name, callable in a single tool call. Generating PNG images from mermaid diagrams is a playbook; upload-attachment-to-confluence-page is a skill it uses. Render-mermaid-to-png is another skill. Patch-page-body-with-image-macro is a third skill.
The progression is the same shape every time.
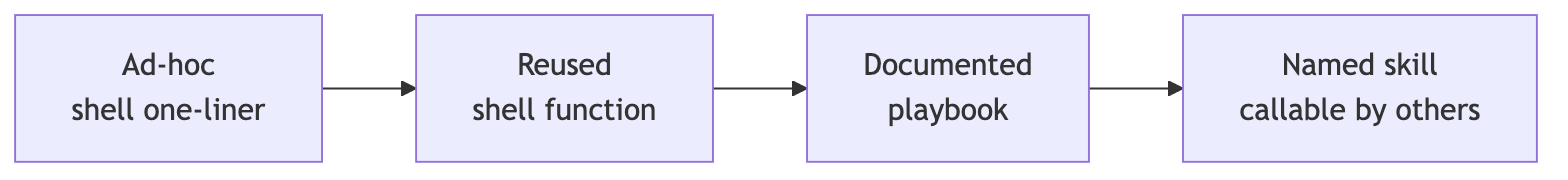
An ad-hoc shell one-liner becomes a shell function once it is called from two places. The function becomes a documented playbook when the sequence around it has phases someone else needs to understand. The playbook's atomic operations become named skills once the operation is reused across playbooks. Each step up the ladder is a real cost (writing, testing, maintaining) and pays off only if the artifact is genuinely reused.
Skills are worth codifying when the operation is stable, testable in isolation, and used from at least two playbooks. Anything else stays in the playbook body as inline steps.
What to codify, what to leave alone
The rule of three is the codification trigger. The countervailing rule is: do not codify the last mile.
Criteria for codifying:
- Is the sequence stable? A sequence that shifts every run has no shape worth writing down.
- Does it have branching worth documenting? If it is three commands in a row, a shell alias is enough.
- Is there value in someone else running it? If only you will ever run it, skip codification. The maintenance cost is real, and a private note is fine.
Criteria for leaving one-off:
- It happens once a year. The reorg itself was one-off. We did not write a how-to-reorg-your-wiki playbook because we will not need one again.
- Judgement calls dominate the mechanics. Naming pages, choosing frameworks, deciding what to archive. Codifying just the mechanics gives false confidence.
- The domain is drifting under you. If the tool, API, or target format is changing fast, a playbook is out of date the week you write it.
The signal we watch for now: the third repeat, plus stability, plus reuse. All three, or leave it one-off.
Closing the loop
Post 1 was the honest-about-what-broke case study. Post 2 was the eight-section framework map. Post 3 was the repo-first sync model. This post is the codification loop that lets any of the above be re-run by a fresh human, a fresh agent, or the same team six months from now when everyone has forgotten the details.
If you take one thing from the series: the interface between human intent and AI execution is a written document, not a Slack thread. The document is a playbook. The playbook is where the leverage lives.


